What a Pilot Can Tell You Before a Wider Decision
A policy pilot can reveal whether delivery is feasible, what gets in the way and which questions remain open before a wider decision is made.
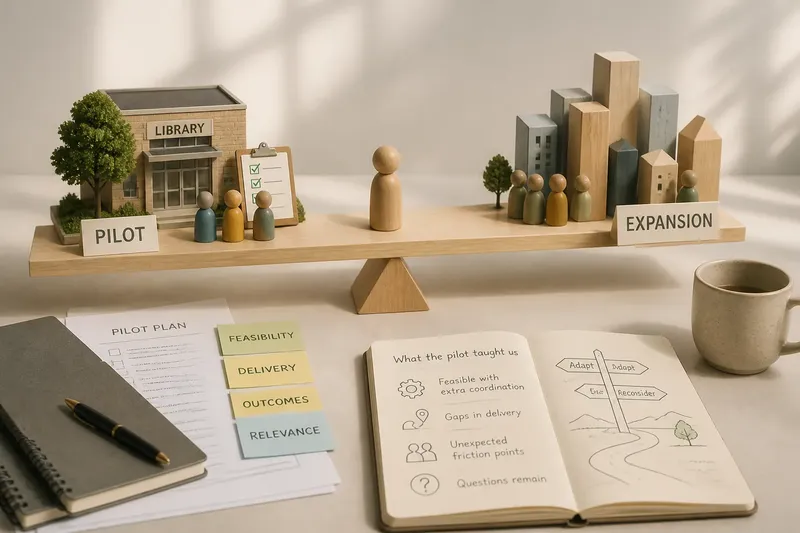
Before a policy pilot is widened, the real question is not simply whether it worked. It is what the trial actually taught decision-makers: whether the service could be delivered, whether the intended people could reach it, and whether its results might carry beyond the trial setting. A pilot can answer some of these questions well and leave others almost untouched.
That distinction matters because a small trial is easy to overread. A smooth launch can be mistaken for proof of broad usefulness; an awkward one can be blamed on the idea rather than its temporary arrangements. Treat the pilot as a source of bounded evidence, not a miniature version of the future with the inconvenient parts removed.
Start with the question the pilot was built to answer
A pilot is most informative when its purpose is specific. “See if this works” is not specific. It could mean checking whether staff can use a new process, whether eligible residents understand an offer, whether agencies can exchange information, or whether the policy changes an outcome that matters.
Those are different questions, and each calls for different observations. If the concern is feasibility, the useful record may include where staff get stuck, what information is missing, and which tasks require workarounds. If the concern is public reach, the record should show who heard about the offer, who tried to use it, and where people stopped.
Read the pilot plan, operating guidance, and review criteria together. Look for a clear statement of what would count as a workable process, what would count as a delivery problem, and what the trial is not designed to establish. A pilot may be able to show that an appointment system can be run in one office; it cannot, by that fact alone, show that the policy improves outcomes across a whole jurisdiction.
When the purpose is vague, reconstruct it carefully from the decisions the pilot was meant to inform. Do not quietly replace an awkward original question with a more flattering one after results arrive. That is less evaluation than editing the question until the answer behaves.
Separate feasibility from successful delivery
Feasibility asks whether the policy can be put into operation under the trial’s conditions. Delivery asks whether the planned service or rule reached people in the intended way. A process may be technically feasible but poorly delivered: the software opens, the office has staff, and residents still receive unclear instructions or cannot get an appointment.
For feasibility, examine the resources and dependencies the trial relied on. Did the service require a specialist staff member, a temporary coordinator, extra reminders, or close attention from senior officials? Were forms, referral routes, and decision rules available when needed? These details help distinguish a routine that can be sustained from one held together by exceptional attention.
For delivery, follow the path from authorization to actual contact. A policy can be approved and formally available without reaching the people it is meant to serve. Check whether frontline staff understood the eligibility rules, whether people were informed in an accessible way, and whether a referral led to a completed service rather than another instruction to call elsewhere.
Imagine a city pilot offering residents help with heating-bill arrears through local libraries. Staff at one branch can explain the service and send referrals, so basic feasibility looks promising. But if residents leave without knowing what documents to bring, the delivery problem is visible even though the referral system is functioning. The useful observation is not simply that the pilot operated; it is where the resident’s path became hard to follow.
Keep records of adaptations made during the trial. A revised form or extra staff briefing may be sensible, but it changes what was delivered. Compare the initial design with the working version and note when each adjustment appeared. Otherwise, a later review may attribute a better experience to a policy design that was not actually in use for the whole pilot.
Read outcomes alongside the route that produced them
Outcome measures matter, but they do not explain themselves. If a pilot reports fewer unresolved applications, ask what else changed in the process. Were cases resolved sooner because the new service helped people, because staff closed incomplete files differently, or because the trial included additional follow-up? The same observed result can have several plausible routes.
Look for a chain of evidence rather than one headline measure: who was eligible, who was reached, who took part, what service they received, and what changed afterward. Each link has its own possible gap. If participation was limited to people already comfortable using online forms, the observed experience may say little about people who avoided the process entirely.
Also distinguish an outcome from a promise about long-term effect. A pilot may observe that people completed an application or received a referral. That is not the same as establishing a lasting change in household stability, health, or income. The further the claim travels beyond the observed period and group, the more carefully it should be stated.
Numbers can be useful, but small trials often make them look more decisive than they are. Read them with counts of who was included, who was missing, and whether the groups being compared were genuinely similar. Notes from staff and participants can explain friction or unexpected consequences; they do not, by themselves, settle how common those experiences were.
Ask what might change when the policy travels
A pilot takes place somewhere, among particular people, with particular staff and surrounding institutions. Wider relevance depends on whether those conditions resemble the places where a larger policy would operate. The central question is not whether a pilot setting is “representative” in the abstract, but which features could alter delivery or results elsewhere.
Compare the trial setting with likely expansion sites. Consider staff capacity, local referral partners, language access, geography, existing caseloads, and the rules that shape who qualifies. A service that relies on a trusted local organization may be harder to reproduce where that organization is absent. A process that works in a staffed office may need a different route in a rural area where residents travel farther.
Some features can be standardized, while others call for local adaptation. The decision should be explicit. If local staff are allowed to change eligibility wording or referral practice, the policy may become easier to deliver but harder to compare across locations. If every detail is fixed, consistency may improve while fit declines. Neither choice is automatically right; the pilot should help identify which elements are essential and which can be adjusted.
Think of the pilot as a key tested in one lock, not a master key. It can show that the shape fits a particular mechanism. It cannot tell you that every door in the building uses the same lock.
How should a pilot inform a wider decision?
What does feasibility mean in a policy pilot?
Feasibility means the policy can be operated under identifiable conditions, with the staff, systems, and authority required. It does not establish that the policy reaches its intended audience or produces a valuable outcome.
Can a small pilot show that a policy works?
It can provide evidence about what happened in the trial and how the process behaved there. Whether those observations support a wider claim depends on the comparison, the people included, the outcome measured, and the differences between trial and expansion settings.
What should decision-makers do when results are mixed?
Separate findings by question: what was feasible, where delivery faltered, and what outcomes remain uncertain. A targeted redesign or a further trial may address a specific gap better than either immediate expansion or a blanket rejection.
When is a pilot too limited to guide expansion?
It may be too limited when the people reached differ sharply from the intended wider population, crucial delivery conditions are missing, or the observed period cannot address the outcome being claimed. State the limit plainly and identify what additional observation would reduce the uncertainty.
Make the next decision match the evidence
A pilot review should lead to a decision that reflects both what is known and what remains open. Options may include stopping, changing the delivery model, extending the trial to a different setting, or expanding with continued monitoring. The choice should connect to the original questions, not to the simple fact that a pilot has ended.
Before expansion, specify what must be preserved, what can be adapted, and what should be watched. For example, a program may need a consistent eligibility rule while allowing local organizations to choose how they explain the service. Monitoring can then track whether access differs by location and whether the adaptations change who participates.
For anyone assessing a policy pilot, the most useful written conclusion is often modest: this part was workable under these conditions; this part reached people unevenly; and this broader claim still needs evidence. That is not a failure of ambition. It gives the next decision a proper boundary, which is rather more useful than confidence without a map.